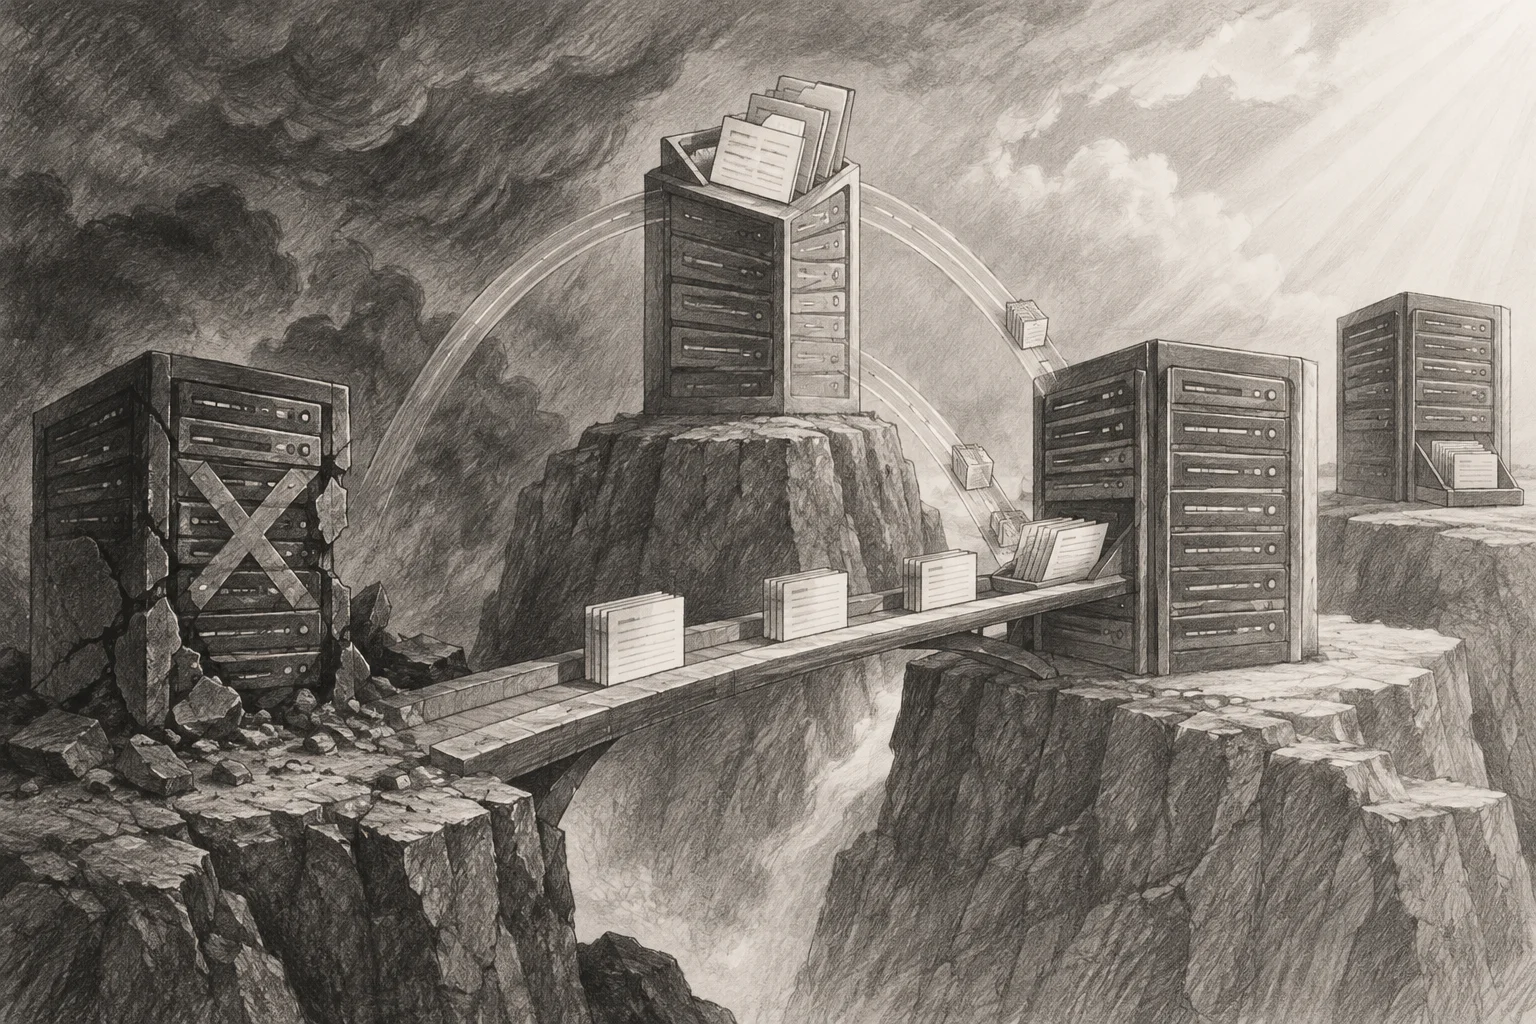
Domino Cluster Failover: No Replica, No Failover
A Domino server goes down, or gets slammed, and users keep working almost without noticing — that’s a cluster doing failover and workload balancing. But failover isn’t magic: it has one hard prerequisite — another cluster server must hold a replica of the database — no replica, nothing to fail over to. Behind it is a set of components working together: each server’s Cluster Manager checks the others are alive, one cldbdir.nsf tracks who has which replica, and a Cluster Replicator keeps the replicas near-synchronized. This piece lays out how they fit together.
TL;DR
- The hard prerequisite: failover relies on another server holding a replica. Officially, the request “is redirected to a replica of the database on a different server in the cluster” — no replica, no failover.
- Cluster Manager (one per server): uses probes to gauge the other servers’ availability and load; finds cluster membership by watching the Domino Directory’s
ClusterNamefield and the membership list. - Cluster Database Directory (
cldbdir.nsf): a replica on every cluster server, with one document per database and replica — failover’s “map” of who has what. - Cluster Replicator: event-driven, near-real-time — on a change it “quickly pushes the change to the other replicas,” checking
cldbdir.nsfabout every 15 seconds; it replicates only among cluster members. Replication with servers outside the cluster is the regular REPLICA task’s job. - How failover goes: when the first server doesn’t respond, the Notes client asks the next cluster member; its Cluster Manager checks
cldbdir.nsf, lists the servers holding a replica, sorts by availability, and sends the list to the client, which opens the most available one — largely transparent to the user. - Workload balancing: set an availability threshold; when a server hits it, the Cluster Manager marks it BUSY and routes requests for its databases to other replicas — but if no other server has a replica, or all are BUSY, the original database opens anyway (busy beats unavailable).
The cluster components
A Domino cluster is held up by a few components (official: the cluster components):
- Cluster Manager: runs on every cluster server. It uses probes to continuously gauge the others’ availability and load, and drives the failover and workload-balancing decisions. How does it know who’s in its cluster? By periodically watching the Domino Directory — the Server document’s
ClusterNamefield and the membership list — so adding/removing a server from a cluster is a Directory change the Cluster Manager picks up. - Cluster Database Directory (
cldbdir.nsf): every server has a replica, listing each database and replica in the cluster (which server, what status). This is the “map” for failover and balancing. - Cluster Database Directory Manager: creates and keeps
cldbdir.nsfcurrent as databases are added, deleted, or change status. - Cluster Administrator: housekeeping — e.g. when a server joins a cluster, it starts the Cluster Database Directory Manager and Cluster Replicator.
- Cluster Replicator: covered next.
The Cluster Replicator: event-driven, near-real-time
Ordinary replication is scheduled (every few minutes or hours). Inside a cluster it’s different: the Cluster Replicator is event-driven — the moment a replica changes, it “quickly pushes the change to the other replicas in the cluster,” keeping them near-real-time in sync. It checks cldbdir.nsf about every 15 seconds for what to push.
Two boundaries to remember:
- The Cluster Replicator replicates only among cluster members; replication with servers outside the cluster is still the regular REPLICA (scheduled replication) task.
- This near-sync is what makes failover useful — the replica you fail over to is current. But for the same reason, on a low-speed WAN, HCL suggests considering turning off cluster replication and using more frequent scheduled replication instead, so near-real-time replication doesn’t swamp the slow link.
(This complements what the replication piece covers about scheduled replication: near-real-time inside the cluster, scheduled outside it.)
How failover goes (from the user’s side)
When the server a user is reaching for doesn’t respond (official: how failover works):
- The Notes client uses its own cluster cache to find the other cluster members and asks the next one.
- That server’s Cluster Manager checks
cldbdir.nsffor which servers hold a replica of the database. - It builds a list of servers with a replica, sorts it by availability, and sends the list back to the client.
- The client opens the most available one; if that’s down too, it tries the next on the list.
HCL puts it this way: although the user connects to a replica on a different server, “failover is essentially transparent to the user.” The prerequisite is always step one: the database has a replica on another server — without that, there’s nothing to fail over to.
Workload balancing: the availability threshold and BUSY
Failover handles “down”; workload balancing handles “too busy” (official: how workload balancing works):
- You set an availability threshold for a server (notes.ini
Server_Availability_Threshold). - When the server gets busy enough to hit the threshold, the Cluster Manager marks it BUSY.
- Requests for databases on that server are then routed to other replicas — spreading the load.
- But there’s a floor: if no other server has a replica, or all cluster servers are BUSY, the original database opens anyway, even though that server is busy. Slow beats unavailable.
- (A separate setting,
Server_Restricted, makes a server refuse new database-open requests — note it blocks only new opens; existing connections are kept, and replication is unaffected — it doesn’t seal the server off entirely.)
For HTTP: the Internet Cluster Manager (ICM)
The above is for Notes clients. Browser (HTTP) clients go through the Internet Cluster Manager (ICM): it applies the same failover and workload-balancing rules, and when several servers remain to choose from, the ICM redirects the client to the most available server (highest availability index) that holds a replica. (Note the availability index is computed from all open sessions, not just instantaneous load — which is why HCL’s wording is “most available,” not literally “least busy.”) So web applications get cluster failover too — just with the ICM as the entry point.
Wrap-up
- Hard prerequisite: failover needs a replica on another server — no replica, no failover.
- Components: Cluster Manager (probes for liveness/load, watches the Directory
ClusterNamefor membership),cldbdir.nsf(a replica per server, one doc per database/replica), Cluster Database Directory Manager, Cluster Administrator, Cluster Replicator. - Cluster Replicator: event-driven, near-real-time (checks ~every 15 seconds), only among members; outside the cluster uses regular REPLICA; on a low-speed WAN you may switch back to scheduled replication.
- Failover: the Cluster Manager checks
cldbdir, lists servers with a replica sorted by availability, sends it to the client, which opens the most available — transparent to the user. - Workload balancing: hit the availability threshold → marked BUSY → route to other replicas; if no other replica or all BUSY, the original opens anyway.
- HTTP: the ICM applies the same rules and picks the most available (highest availability index) server holding a replica.
Sources
- The cluster components (Cluster Manager, cldbdir.nsf, Cluster Database Directory Manager, Cluster Administrator, the event-driven Cluster Replicator checking ~every 15 seconds, REPLICA for outside the cluster) — HCL Domino (official)
- How failover works (requires a replica on another server, the Cluster Manager builds and sorts a list of servers with a replica and sends it to the client, transparent to the user) — HCL Domino (official)
- How workload balancing works (availability threshold, marking BUSY, routing to other replicas, original database opens if all are BUSY or no other replica) — HCL Domino (official)